Introduction
This study, carried out by Juliette Jourdan as part of an internship, was aimed at evaluating and refining FireML, a machine-learning algorithm developed by SERTIT for the rapid delineation of burned areas from mono-temporal Sentinel-2 imagery in operational emergency mapping contexts. The objective was to identify the main factors limiting performance and to assess potential improvements related to spectral indices, sampling strategies, and classification models.
Methodology
FireML uses Sentinel-2 imagery and derives several spectral indices to classify pixels as burned or unburned. The original workflow relies on an automatic sampling procedure based on the HSV (Hue–Saturation–Value) colour space (Figure 1).
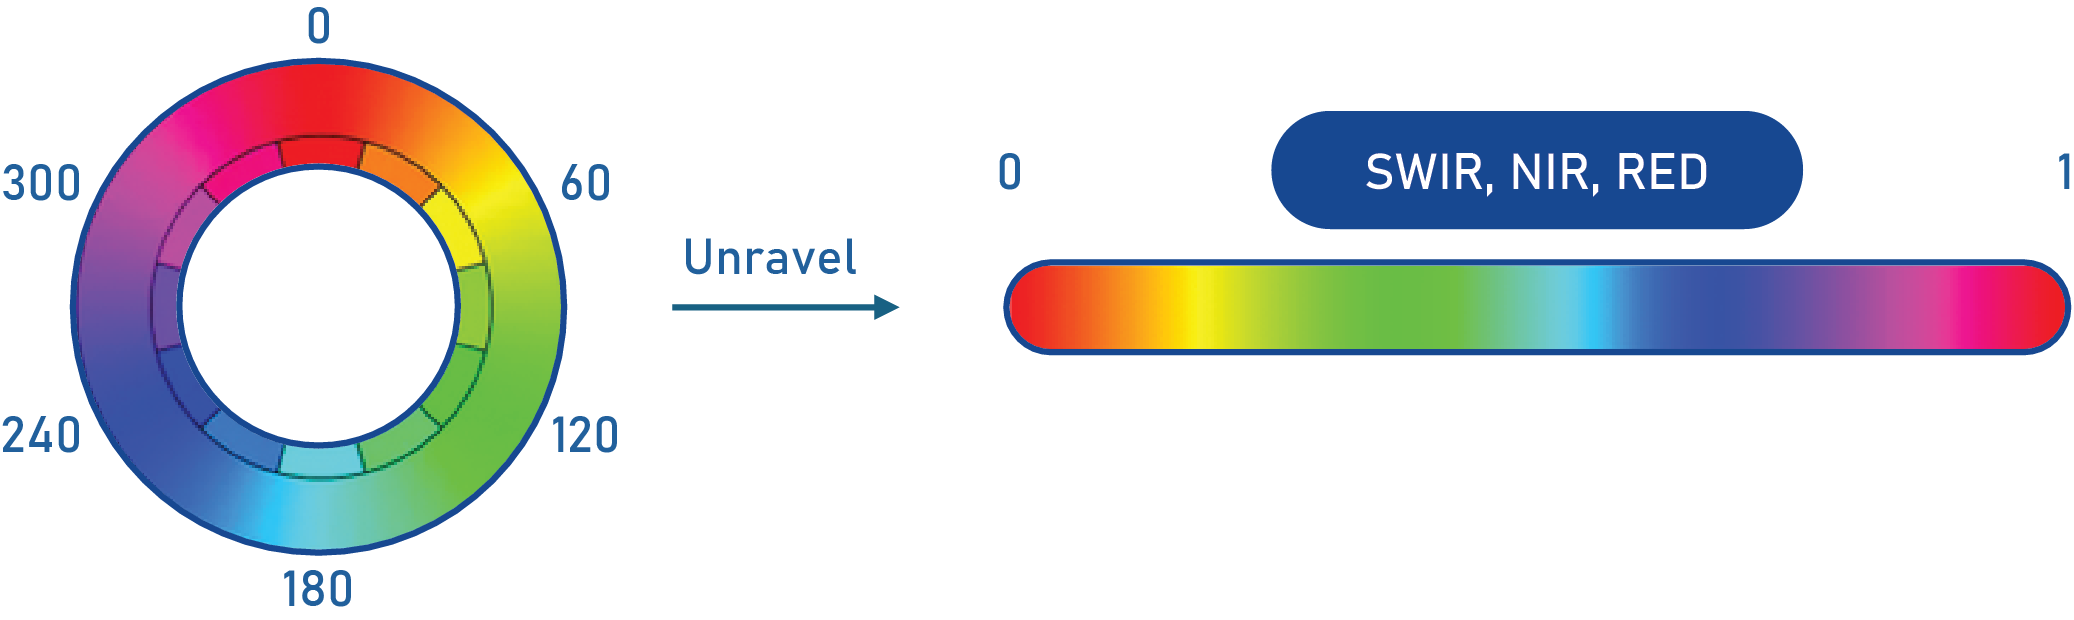
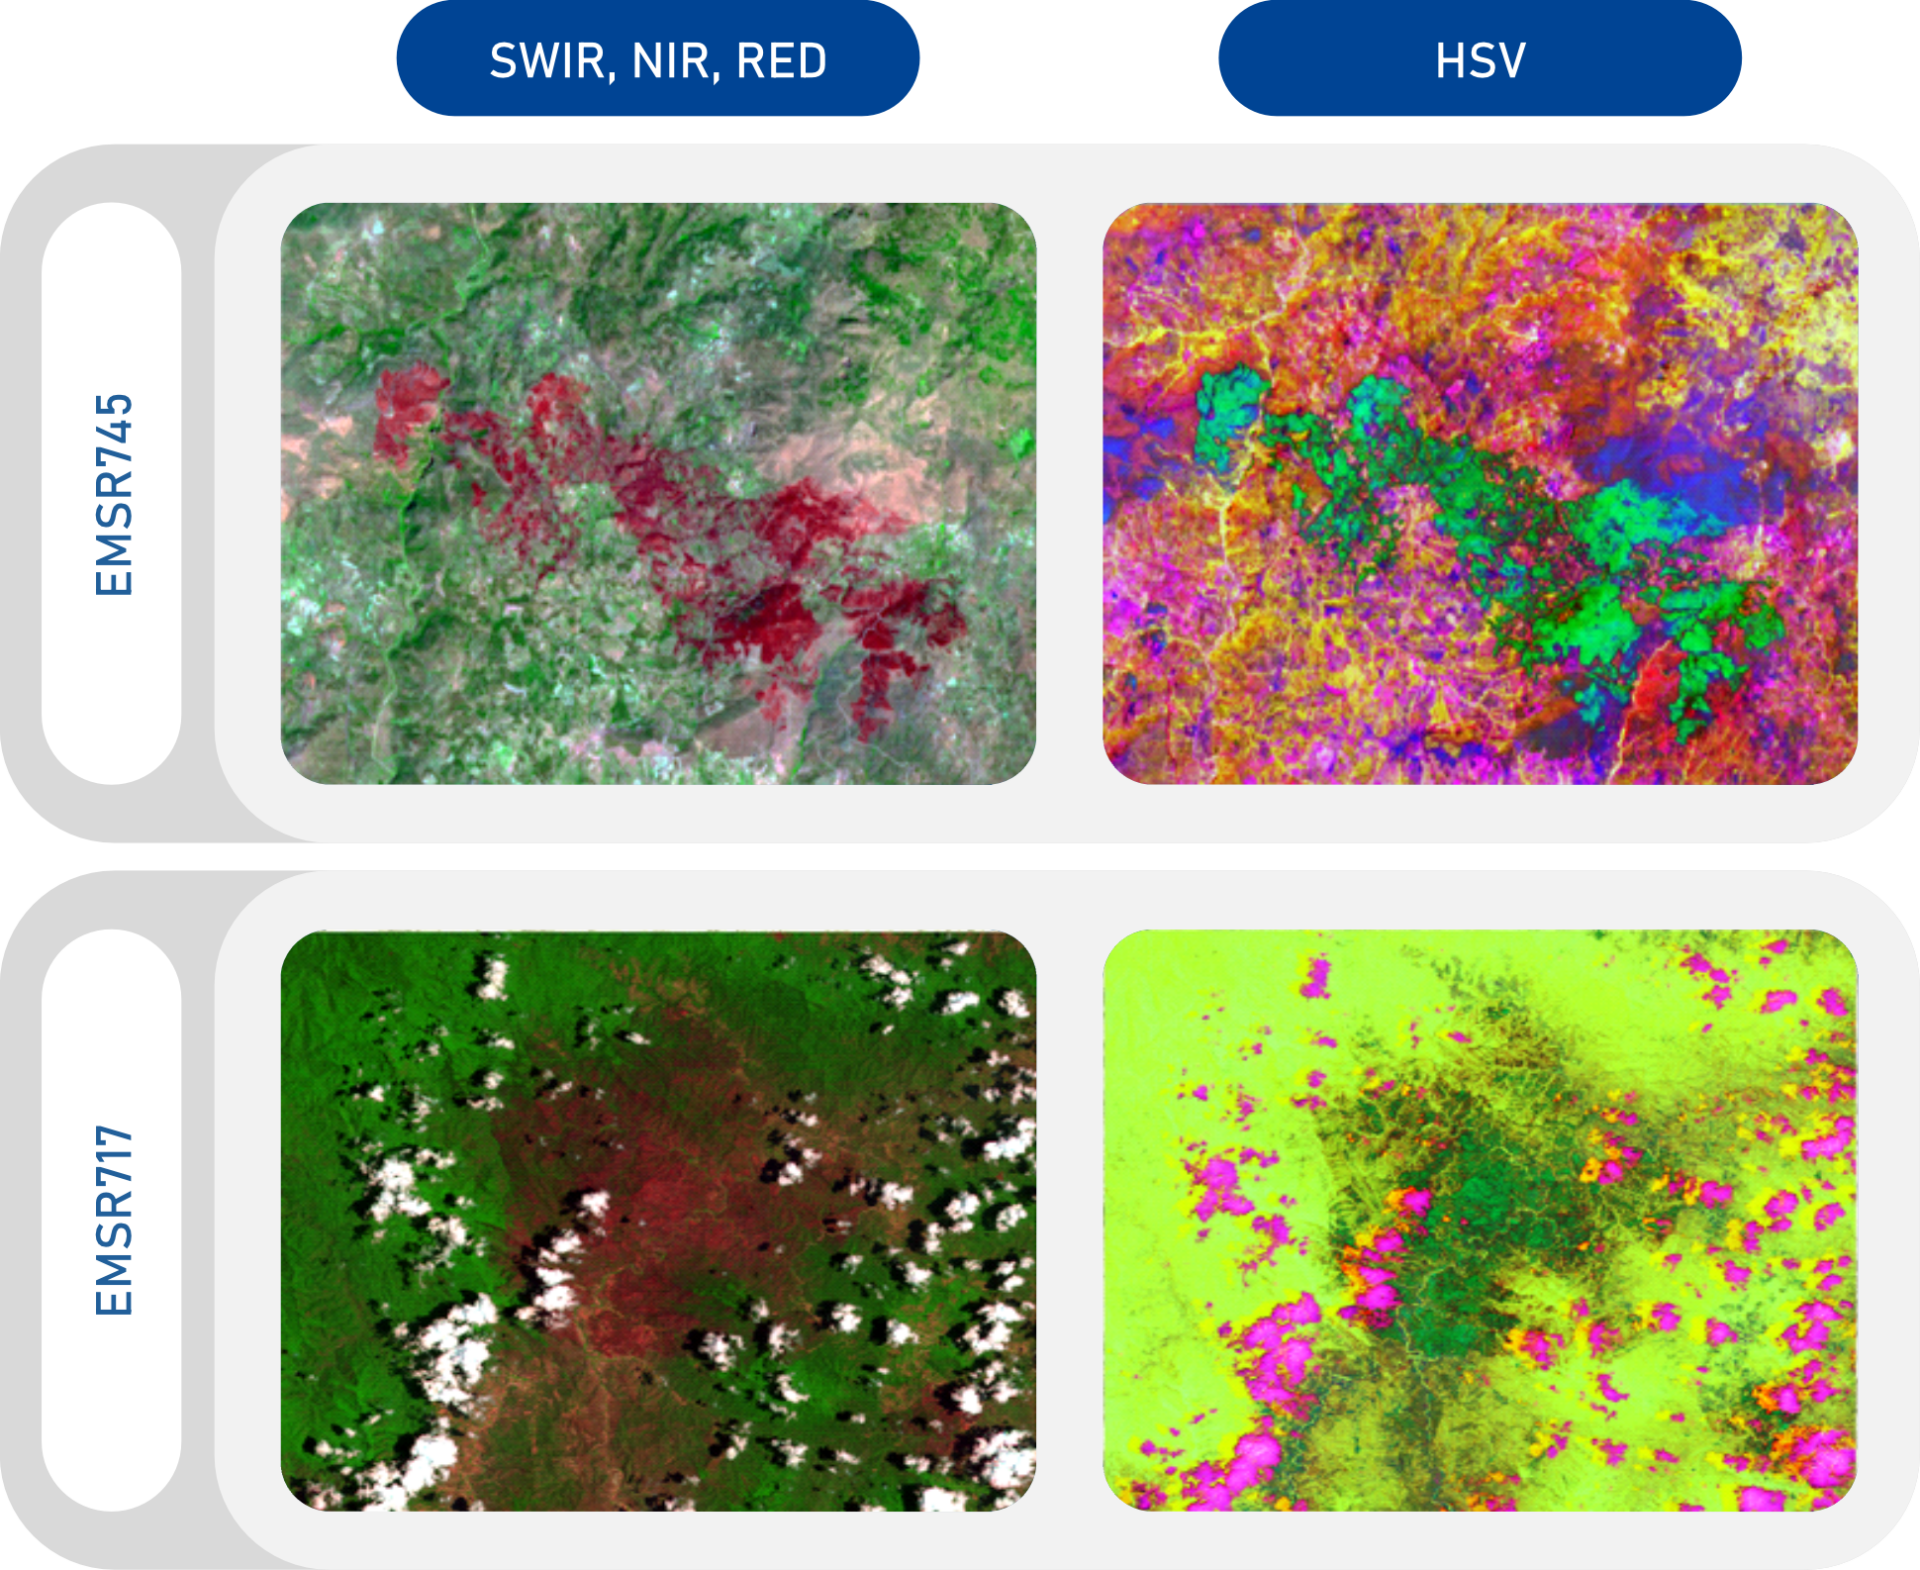
Sentinel-2 SWIR2, NIR, and Red bands are transformed into HSV, and only the Hue component is used to generate training samples. Hue was selected because it provides good visual separation between burned and unburned surfaces, while Saturation and Value contribute little additional discrimination and are mainly useful for visual interpretation (Figure 2).
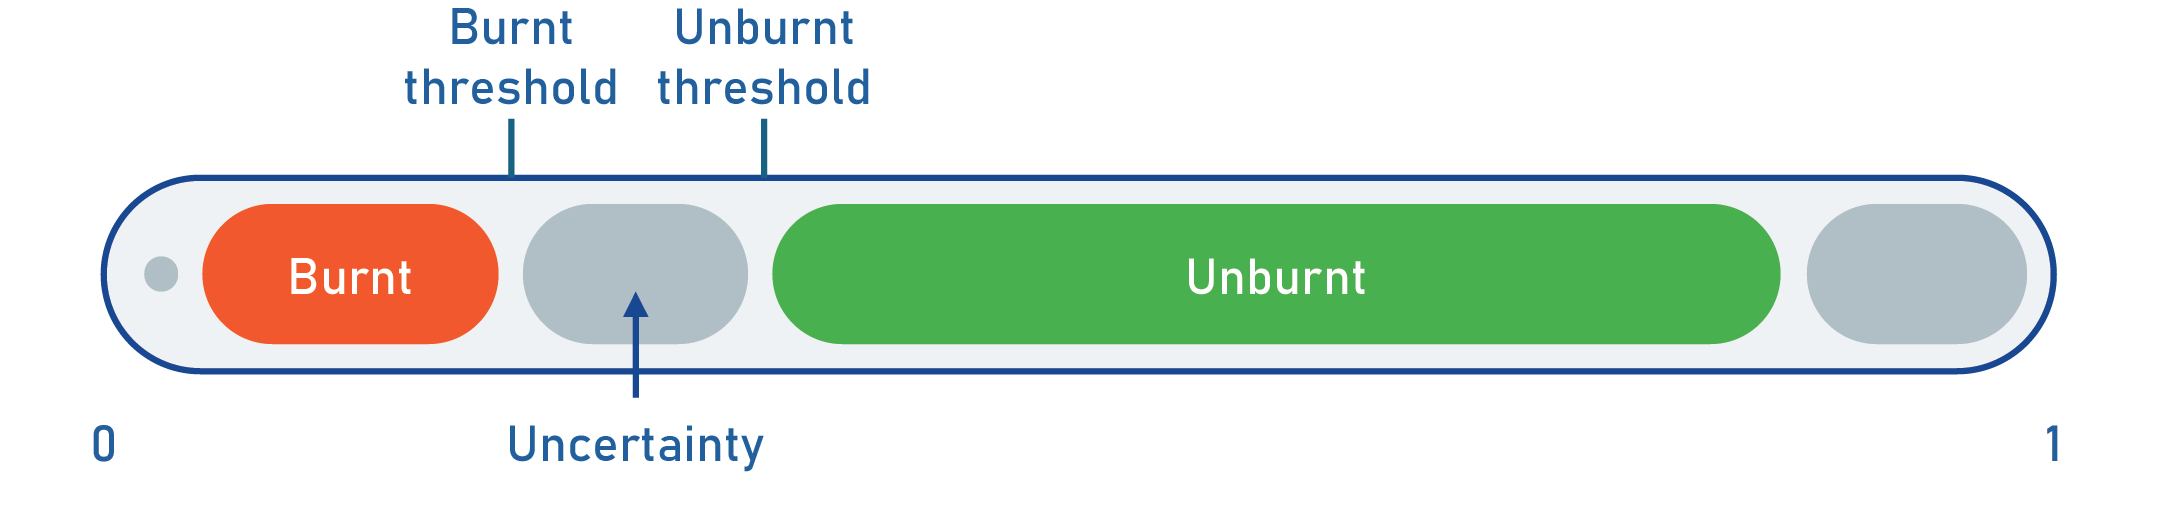
From the normalised hue, generic thresholds were defined by analysing the statistical distribution of hue values for burn scars, across several use cases (Figure 3).
These samples were then used to draw values from spectral indices, and passed to a one-shot classification model, corresponding to a shallow multi-layer perception (MLP) to accelerate production under the tight constraints of emergency mapping. The initial set of indices, selected from empirical a-priori knowledge, corresponded to NBR, NBR2, BAIS2 and BITM.
The study carried out during this internship evaluated three components of FireML:
- Spectral indices used as input variables.
- Sampling strategy, which generates training data automatically.
- Machine-learning model, comparing the existing Multi-Layer Perceptron (MLP) with a Random Forest (RF).
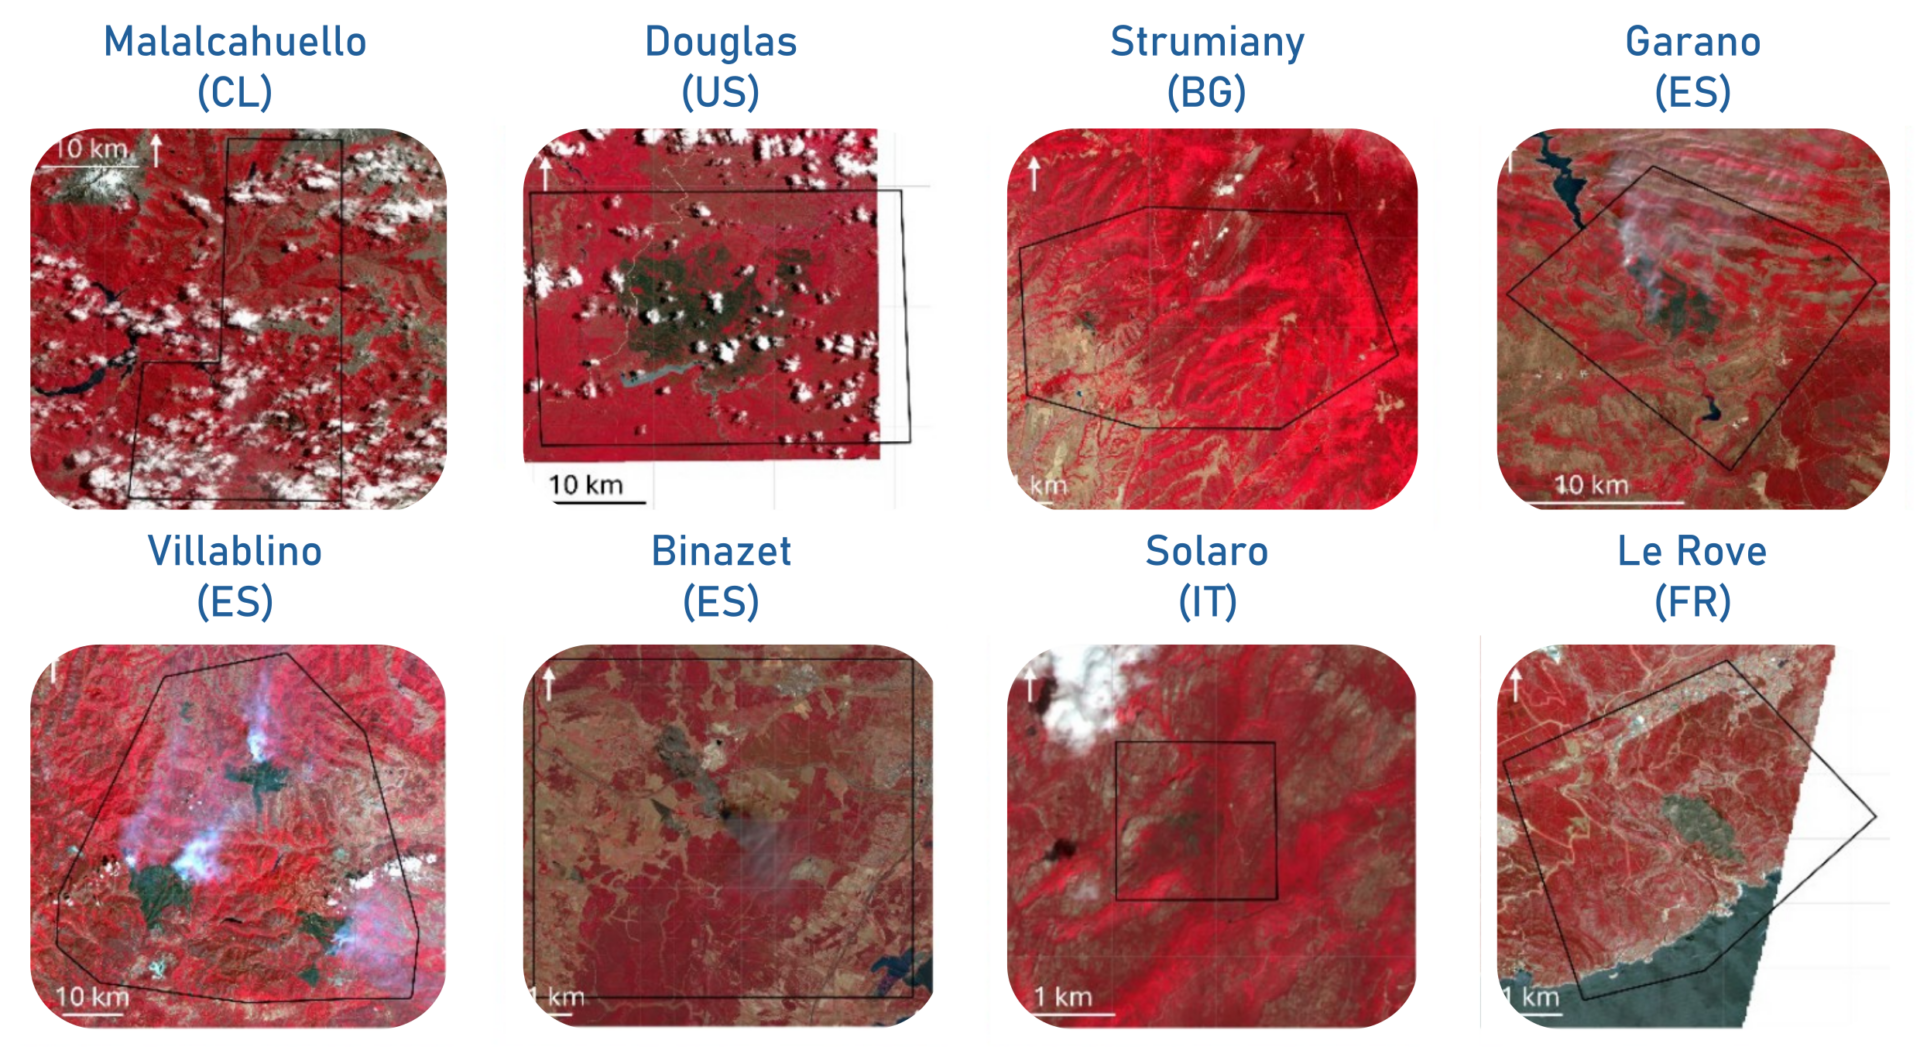
Eight wildfire case studies covering different geographic and environmental conditions were analysed, across Chili (Malalcahuello), Belize (Douglas da Silva), Bulgaria (Strumiany), Spain (Garano and Villablino) and France (Binazet, Solaro and Le Rove). These cases were part of past Copernicus EMS Rapid Mapping and France2030 FireWatch activations (Figure 4). Model performance was assessed using precision, recall, F1-score, Intersection over Union (IoU), and processing time.
Results
Spectral indices
Several burned-area indices identified in the literature were tested alongside the original FireML feature set. The most effective configuration combined NBR2, BITM, and MLSWI27, producing a modest improvement, with recall increasing by approximately 15% while maintaining similar precision. However, no tested index combination substantially improved the most challenging cases. Scenes with poor performance in the original version generally remained problematic after index optimisation.
These findings indicate that spectral features are important but are not the primary factor limiting overall performance.
Sampling strategy
The strongest relationship observed throughout the study was between sampling quality and final model performance. High sampling precision consistently led to higher classification precision, while broader spatial coverage of burned areas improved recall.
The original HSV-based sampling method showed several weaknesses. Although Hue provides a practical way to exploit colour information, it is not specifically related to burned-area detection. Similar Hue values were frequently observed over roads, bare soil, water bodies, shadows, clouds, and built-up areas, generating numerous false positives. In addition, the Hue-based thresholds tended to favour strongly burned surfaces, resulting in insufficient representation of lightly burned areas and consequently lower recall.
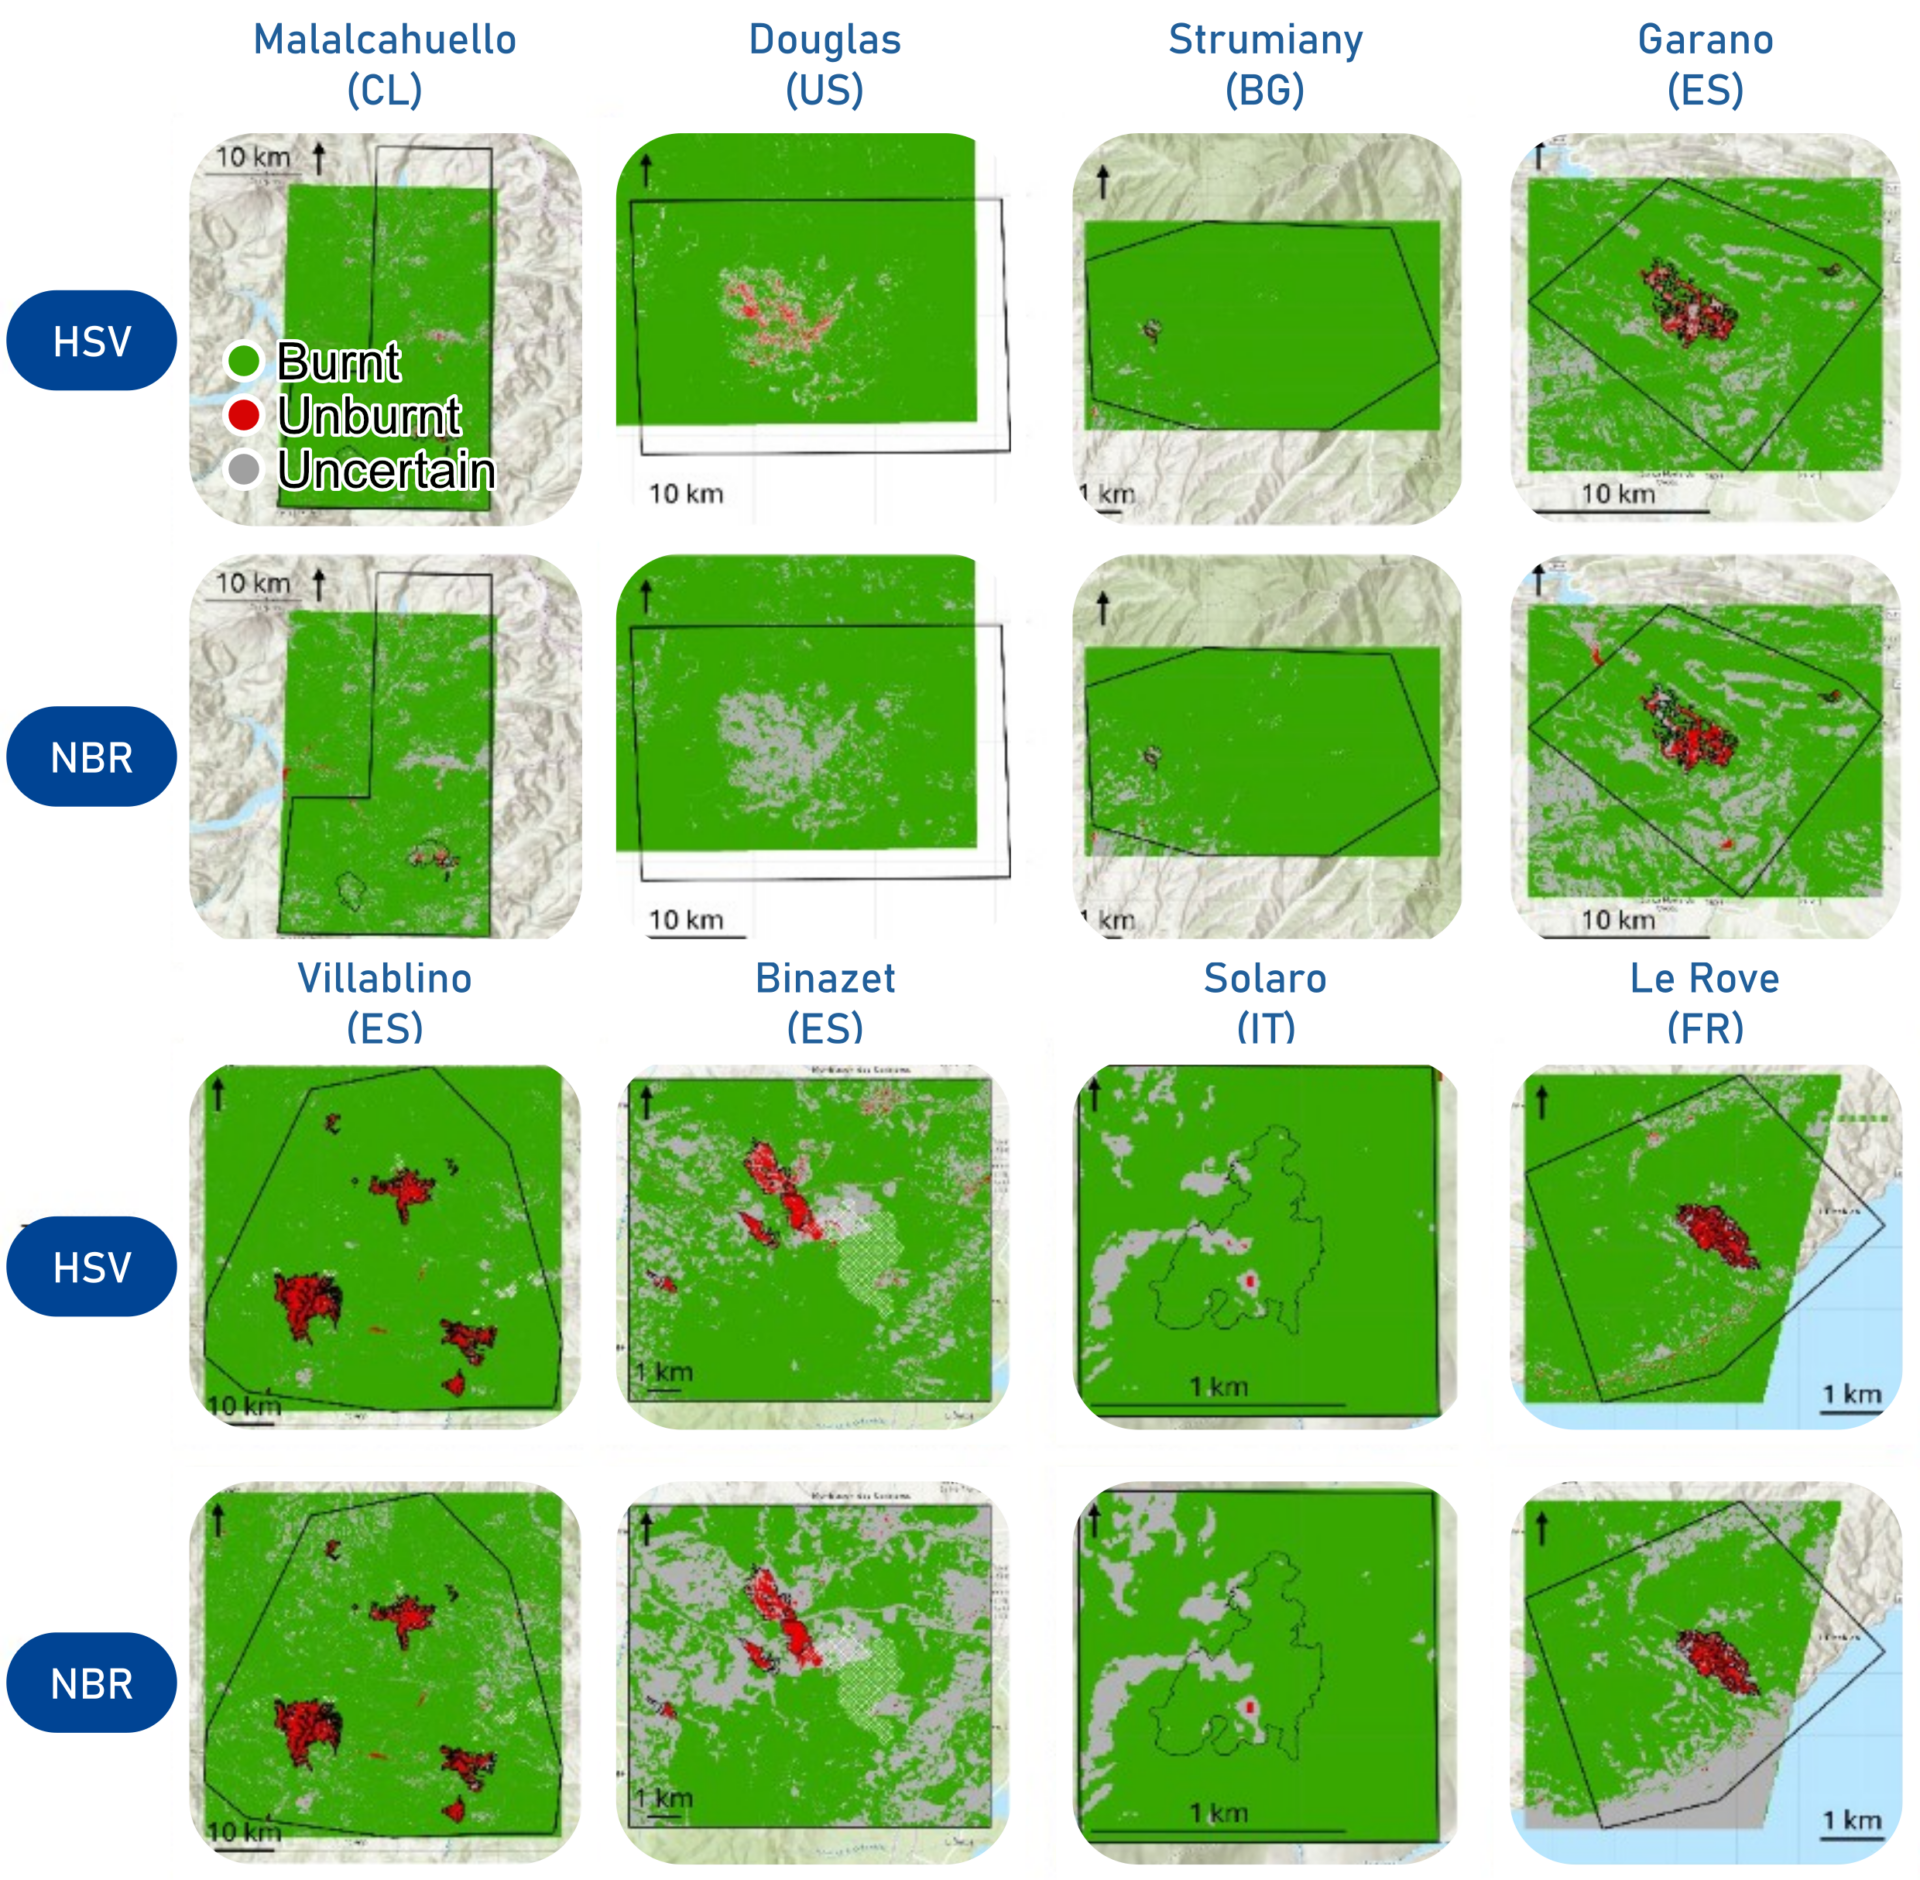
To address these limitations, the HSV sampling approach was replaced with a sampling strategy based on the Normalized Burn Ratio (NBR). While NBR reduced some false positives and improved the detection of certain heavily burned areas, the overall gains remained limited. The method still relied on a single global threshold and therefore struggled to accommodate the full variability of wildfire conditions. No significant improvement over the original HSV-based workflow was achieved (Figure 5).
Machine learning model
The MLP currently implemented in FireML was compared with Random Forest using multiple spectral-index configurations. The Random Forest produced slightly higher recall in some cases but generally at the expense of precision. Overall differences between the two models were negligible in terms of accuracy and processing time.
The results suggest that both models converge toward similar decision boundaries because the spectral indices already provide highly discriminative information. Consequently, model selection has a limited impact compared with feature selection and sampling quality. The existing MLP therefore remains an appropriate choice for operational use.
Discussion and conclusions
Several limitations influenced the results. Ground-truth delineations were themselves subject to uncertainty because they were produced under operational time constraints. Technical issues within FireML also affected some case studies, including failures related to sampling outside image boundaries and unusually long processing times for very large areas of interest. Dataset size variability further complicated the interpretation of performance metrics.
Despite these limitations, a clear conclusion emerged: improvements to spectral indices and classification models produced only incremental gains, whereas sampling quality consistently governed the success or failure of the algorithm. The current HSV-based approach is effective for visualisation but insufficiently robust for automatic training-sample generation across diverse wildfire scenarios.
Future work should therefore focus on developing alternate sampling strategies, such as multi-threshold approaches or the integration of multiple spectral indicators during sample selection. Such methods may improve both sample representativeness and model generalisation, offering greater benefits than further optimisation of the classification model itself.